By William Koch, AI for Accelerating Invention Graduate Fellow
ScenarioControl was presented at ECCV 2026.
Developing an autonomous vehicle means preparing it for a world where everything is unique. Roads differ in geometry, traffic changes from moment to moment, and the same intersection can present very different challenges depending on the weather, visibility, and behavior of nearby drivers and pedestrians. More importantly, errors in autonomous driving can have severe consequences, including the loss of life.
Now, research on autonomous driving can broadly be divided into three areas: the development of (a) hardware sensors for measuring, (b) algorithms for understanding (vision), and (c) algorithms for acting upon that information (driving policy) the environment. To develop (c), we need a lot of data, which is why modern autonomous driving stacks are trained on tens of millions of real-world miles. But the events most important for safety are often the hardest to collect. A wrong-way driver, a pedestrian emerging from behind a truck, or an unusual merge may occur only rarely, and a handful of recorded examples cannot capture every meaningful variation.
The standard response has been to build simulators. Tools like CARLA and MetaDrive let engineers hand-design the exact situations they want to stress-test. But creating handcrafted worlds is costly, hard to tweak, and – as anyone who has compared simulators with real dashcam footage knows – they look nothing like reality. We can broadly split this into two problems: creating the traffic agents and layout, and creating a photo-realistic synthetic dashcam video (and other synthetic sensor data) that corresponds to this layout.
For the first problem, generative systems such as SLEDGE and Scenario Dreamer can synthesize lane graphs and traffic participants. However, the scenes they generate are sampled from the real-world distribution. They do not offer the fine-grained controls needed to systematically create challenging edge cases.
For the second problem, diffusion-based world models have made significant progress in recent years. Systems such as GAIA-2 and Cosmos-Drive-Dreams can generate realistic driving videos, even conditioned on layouts. But those layout controls such as road layout and vehicles need to be specified first. The models can render a specified scenario convincingly; they do not themselves provide that scenario.
What we want is a tool that lets researchers describe a driving scenario in natural language – or show it a single image – and get back a structured, simulation-ready 3D scene that is both controllable and photorealistic. That is the core of what we worked on.
ScenarioControl: A Latent Space of Roads, Agents, and Signals
Our paper, ScenarioControl: Vision-Language Controllable Vectorized Latent Scenario Generation, introduces the first vision-language control mechanism for learned driving scenario generation. Given a text prompt or a single RGB frame, ScenarioControl produces a full vectorized 3D scenario: lane centerlines, traffic lights, static infrastructure, and the 3D bounding boxes of reactive agents over time. The same scene can then be rolled out by an off-the-shelf behavior simulator and rendered into photorealistic video.
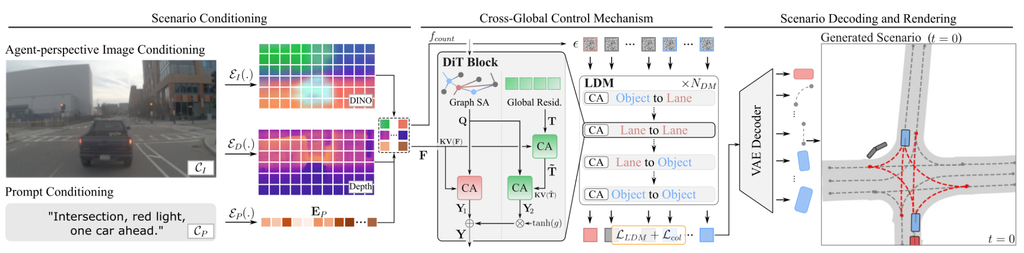
The core idea to allow for control and simulation is to keep the scene vectorized. That is, instead of generating a grid of pixels or voxels, ScenarioControl works on a sparsely-connected graph of lane segments and agents inside a 64-by-64-meter bird’s-eye view patch. Each element carries an elevation and height term so that the layout can be projected back into camera space (i.e., what the scene looks like from the car, rather than from above). A transformer-based vectorized autoencoder compresses this graph to a latent of about sixteen tokens per element, and a latent diffusion model learns to denoise those tokens conditioned on control signals.
The technical challenge: connecting dense evidence to a sparse graph
When first looking at it, conditioning a diffusion model on text or images is a solved problem – that is what Stable Diffusion and the rest of the generation literature do every day. ScenarioControl has a different alignment problem. A prompt or image produces a dense sequence of features, while the output consists of a variable number of lane and agent elements. A single lane may depend on several distant image regions; an intersection type may depend on the scene as a whole; and some agents may be occluded or outside the camera’s field of view.
Standard cross-attention can, in principle, learn these relationships. The issue is not that it is mathematically incapable of doing so. Rather, it provides little built-in structure for summarizing global context and can be data-inefficient for this dense-to-sparse mapping. We create a modified version, a cross-global control mechanism, that addresses this. One branch is standard cross-attention between scene tokens and conditioning features. A second, lightweight branch introduces a small number of learned latent tokens that aggregate global context from the conditioning; the scene tokens then cross-attend to these compressed summaries. The two branches are mixed with a learned gate, initialized so that the global branch contributes nothing at the start of training and the model behaves like plain cross-attention. During training, the gate learns to open exactly as far as global context helps.
Two other ingredients matter. A small count-injection head predicts how many lanes and agents a scene should contain from the conditioning alone, removing an important degree of freedom at inference time. And a differentiable collision penalty decodes intermediate latents and penalizes overlapping agent boxes during denoising, discouraging the model from generating cars inside one another when prompts are ambiguous.
What You Can Do With Scenario Control
Image-conditioned generation
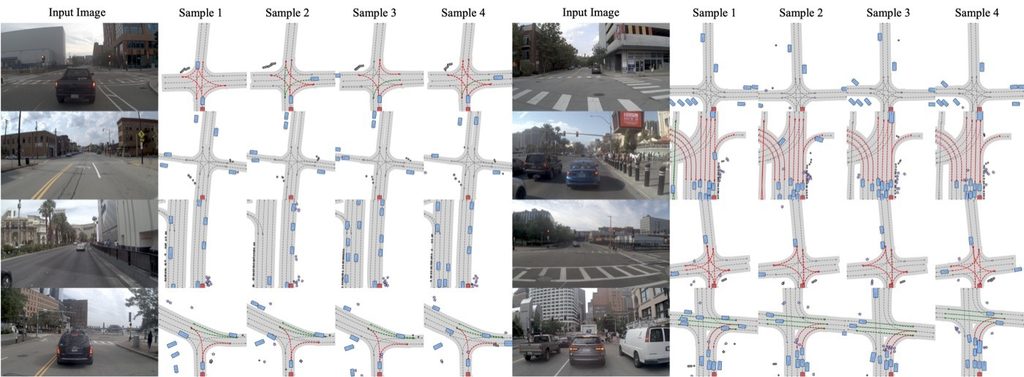
Given a single forward-facing dashcam frame, ScenarioControl infers a plausible vectorized driving scene: the right number of lanes, a matching intersection type, and agent placements consistent with what is visible in the image – while filling in coherent structure for the parts of the world the camera cannot see.
Prompt-conditioned generation
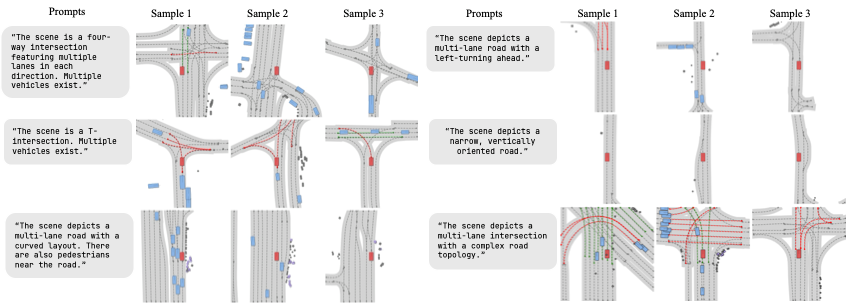
Alternatively, scenes can be created from natural language. The prompt doesn’t have to be elaborate to create diverse examples. Even a short description already allows generation of various scenes.
Outpainting to entire neighborhood-sized layouts
Although the diffusion model is trained on local 64-meter patches, iteratively outpainting new patches around a generated seed produces coherent road networks that span entire city blocks, with consistent topology across block boundaries. A single prompt (“a residential neighborhood with T-intersections and low traffic density”) becomes an entire drivable map.
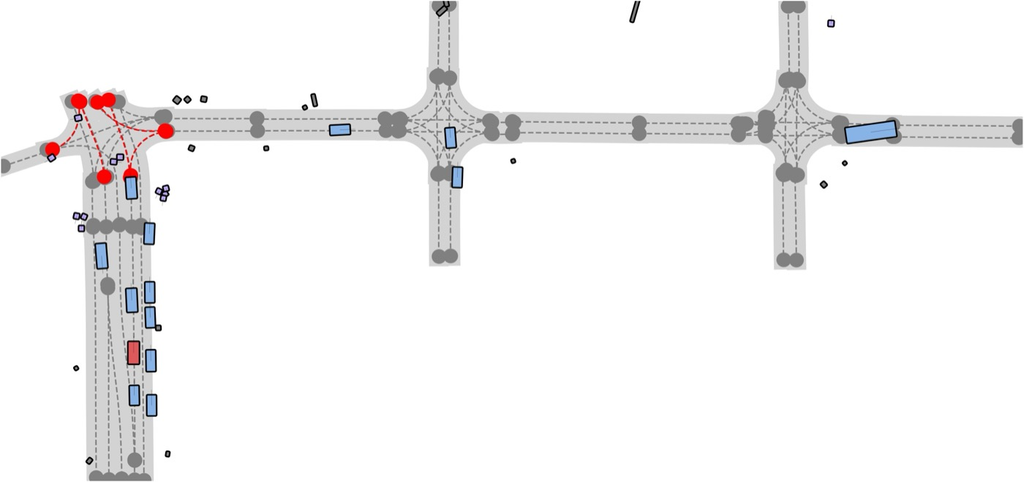
Control improves realism of video generation
Because ScenarioControl produces structured BEV scenes (BEV: birds-eye-view, i.e., top-down view), we can hand them to an existing traffic behavior simulator, roll the agents forward in time, and project the resulting trajectories into any camera in the scene as wireframe control signals. We fine-tune a video model to accept these control signals using LoRA (low-rank adaptation, an efficient method for finetuning large models): This model can then render the rollout, conditioned either on the original dashcam frame or on a text description of appearance. The same underlying scenario can be re-rendered as “a partly cloudy afternoon,” “an overcast rainy morning,” or “a snow-covered rural road.”
Now, video generation models do not strictly need a wireframe control signal (i.e., where to place agents) to generate driving videos – we use that for controllability. However, one interesting observation we made during our experiments was that wireframe control improves the realism of the generated videos – regardless of whether we condition the video on an initial frame, or a description. We measure this using FID and FVD (Fréchet Inception and Video Distance, respectively). These standard metrics capture how closely generated images and videos resemble real data in terms of visual appearance and, for FVD, temporal dynamics. With wireframe control, FID improves by 2.1% and 70.2% and FVD by 43.6% and 69.8% for the first-frame- and prompt-conditioned variants, respectively. The gains are largest for the prompt-conditioned model, where the wireframe provides explicit geometric grounding that text alone underspecifies. These results show that grounding generation in the reprojected vectorized scene improves both appearance and motion realism, rather than trading realism for controllability.
How Well Does It Work?
Beyond “visual appeal,” we assessed whether generated global layouts, lanes, and agents change in the intended way when the conditioning input changes. We found that across three complementary controllability metrics, ScenarioControl improves over the primary baseline, Scenario Dreamer (a prior generative simulator that uses latent diffusion to generate vectorized driving scenes). in both text- and image-conditioned experiments on nuPlan, a large-scale autonomous driving dataset.
For prompt-conditioned generation, we created a new dataset that aligns traffic scenes with text descriptions (see below for details). Here, ScenarioControl improved all nine reported control measures over ScenarioDreamer, with relative gains of up to 143% on individual control-adherence measures.
In a separate, narrower comparison, we held the road map fixed and only generated agent placement. On 14,688 Waymo test scenes, the text-conditioned model achieved 26.8% precision, compared with 5.5% for the TrafficGen baseline.
A New Dataset For Conditional Generation Research
One practical blocker for this line of work has been the lack of vision-language-aligned driving data: Most public datasets either have no captions or have captions tied to raw images rather than vectorized maps. We release a curated set of roughly 500,000 scene-level captions aligned with the vectorized maps of nuPlan, generated by rendering BEV visualizations and prompting a GPT-4.1-mini captioner for scene descriptions that mention intersection type, lane structure, signals, and pedestrians. We hope this dataset is useful well beyond our paper. It can be downloaded here.
The Bigger Picture
ScenarioControl shortens the path from a human idea to a testable virtual world: Describe a situation, generate an explicit scene graph, simulate its participants, and render what different actors might observe.
That workflow could make it easier to create targeted sets of scenarios instead of waiting for them to appear in a driving log or authoring each variant by hand. It could also support research on completing partially observed scenes and imagining multiple plausible situations beyond an agent’s line of sight.
The broader lesson is that useful generative systems do not always need to choose between structure and realism. By generating an editable world first and pixels second, ScenarioControl offers a route toward simulations that are both easier for people to specify and more useful to downstream autonomy tools.
Acknowledgments
The work on ScenarioControl was conducted by Lili Gao1*, Yanbo Xu2*, William Koch2*, Samuele Ruffino1, Luke Rowe3, Behdad Chalaki1, Dmitriy Rivkin1, Julian Ost1,2, Roger Girgis1,3, Mario Bijelic1,2, Felix Heide1,2.
1Torc Robotics, 2Princeton University, 3Mila; * denotes equal contribution.
Felix Heide was supported by an NSF CAREER Award (2047359), a Packard Foundation Fellowship, a Sloan Research Fellowship, a Sony Young Faculty Award, a Project X Innovation Award, an Amazon Science Research Award, and a Bosch Research Award. Felix Heide is a co-founder of Algolux (now Torc Robotics), Head of AI at Torc Robotics, and a co-founder of Cephia AI.
Leave a Reply